Lightreason Releases Local Inference Lab Claiming Up to 11x Speedup for Qwen Models on RTX 4090
A new open-source lab project aims to drastically accelerate Qwen model execution locally on a single consumer GPU through specialized caching and hardware execution techniques.
Photo: Hacker News Front Page
Key points
- Lightreason lab releases local inference toolkit for Qwen models on a single RTX 4090.
- Achieves dramatic speedups using techniques like CUDA graphs, draft-assisted token verification, and hybrid CPU-GPU weight routing.
- Project is available on GitHub with an interactive Live Studio web interface for comparative benchmarking.
A new developer project called Lightreason has introduced a local inference studio designed to run Qwen models significantly faster on a single Nvidia RTX 4090 consumer graphics card. According to the project documentation, the setup applies to the original BF16 weights for both the smaller Qwen2.5-3B-Instruct model and the text components of the larger Qwen3.6-35B-A3B model. By combining existing optimization frameworks such as Nvidia CUDA Graphs, AMD PARD2, Inco AI DFlash2, and FlashML with custom routing changes, the repository reports performance gains reaching up to eleven times faster than standard execution.
The system works differently depending on the model scale. While the smaller 3B model fits entirely onto the GPU where repeated operations and token checking save time, the larger 35B model requires a hybrid system architecture. Because its weights occupy over 64 gigabytes, the runner keeps the majority of expert weights in system host RAM, dynamically streaming only the active weights required by Qwen during generation.
Developers can test the performance using an interactive Live Studio interface that streams standard versus optimized responses side by side. The public release includes source code, pinned download manifests, and benchmark tooling, though users must supply their own model weights and adhere to the official Qwen licensing terms.
What to watch next: Monitor whether these hybrid CPU-GPU execution methods are integrated into broader open-source inference engines for consumer hardware.
Source Hacker News Front Page — github.com/me-farza/lightreason/tree/main ↗
Read next
 🧠AI Analysis
Pedestal AI Secures Seed Funding to Automate Logistics With Intelligent Agents
Pedestal AI has launched publicly with $4.7 million in seed backing to deploy agentic artificial intelligence aimed at streamlining logistics and supply chain operations.
 🏢Big Tech
United Launch Alliance Investigates Vulcan Rocket Failure
United Launch Alliance is investigating a mission failure of its Vulcan rocket, which suffered from low booster performance shortly after liftoff. The incident raises que…
 🌐Work & Society
US Southwest Hydropower Output Hits Record Lows Amid Persistent Drought
Hydropower generation in the US Southwest dropped 28% below the 10-year average this summer as record-low water levels in the Colorado River Basin threaten regional energ…
 🏢Big Tech
YouTube Updates View Metrics to Include TV Co-Viewing Estimates
YouTube is incorporating estimated co-viewing data into its public view counts to better reflect group consumption on television sets.
 ⚖️Regulation & Policy
OpenAI Partners with Chilean Ministry to Advance Public Sector AI
OpenAI has signed a non-binding agreement with Chile's science ministry to integrate artificial intelligence into public administration and support local startups.
 🌐Work & Society
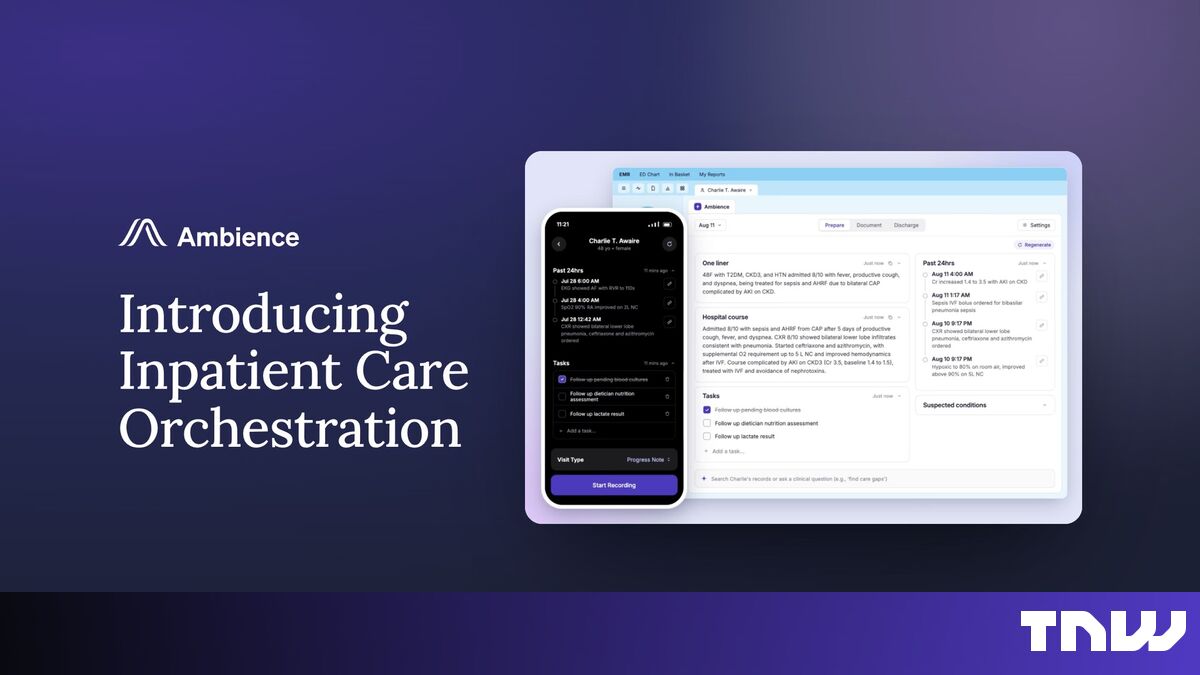
Ambience Healthcare Expands Clinical AI Suite for Hospital Operations
Ambience Healthcare has launched new AI tools designed to assist hospital staff with patient rounding and discharge planning, aiming to improve both clinical efficiency a…